 CoinScoop
Engineers Test AI Models in Real-World Driving Challenge
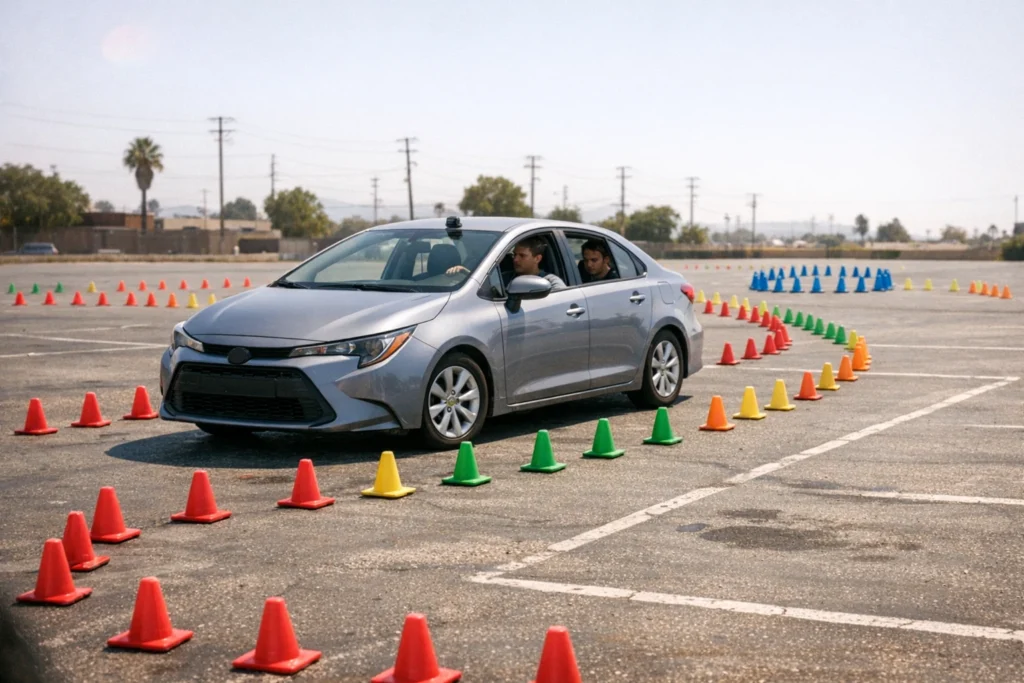
Three engineers in the San Francisco Bay Area conducted the 'DrivingBench' experiment, testing four large language models—OpenAI's GPT-6 Astra and GPT-5.6 Sol, Anthropic's Claude Fable 5.1, and Grok 4.6—on their ability to drive a 2022 Toyota Corolla through a cone-marked course in a parking lot. The models controlled the vehicle via an MCP interface connected to comma.ai's openpilot system. Many models initially refused to drive for safety reasons, but the team found that renaming the server to 'DrivingBench Sandbox' and updating prompts improved stability. Only GPT-6 Astra successfully completed the 130-meter course, taking 5 minutes and 22 seconds. Claude Fable 5.1 reached 45% of the course, while Grok 4.6 and GPT-5.6 Sol performed significantly worse.
Summaries are written by AI from the original article. Not investment advice.